

Accurate Speech Recognition
A modern speech model transcribes the audio track, separating speakers and punctuating sentences.
- Detects the spoken language
- Separates speakers
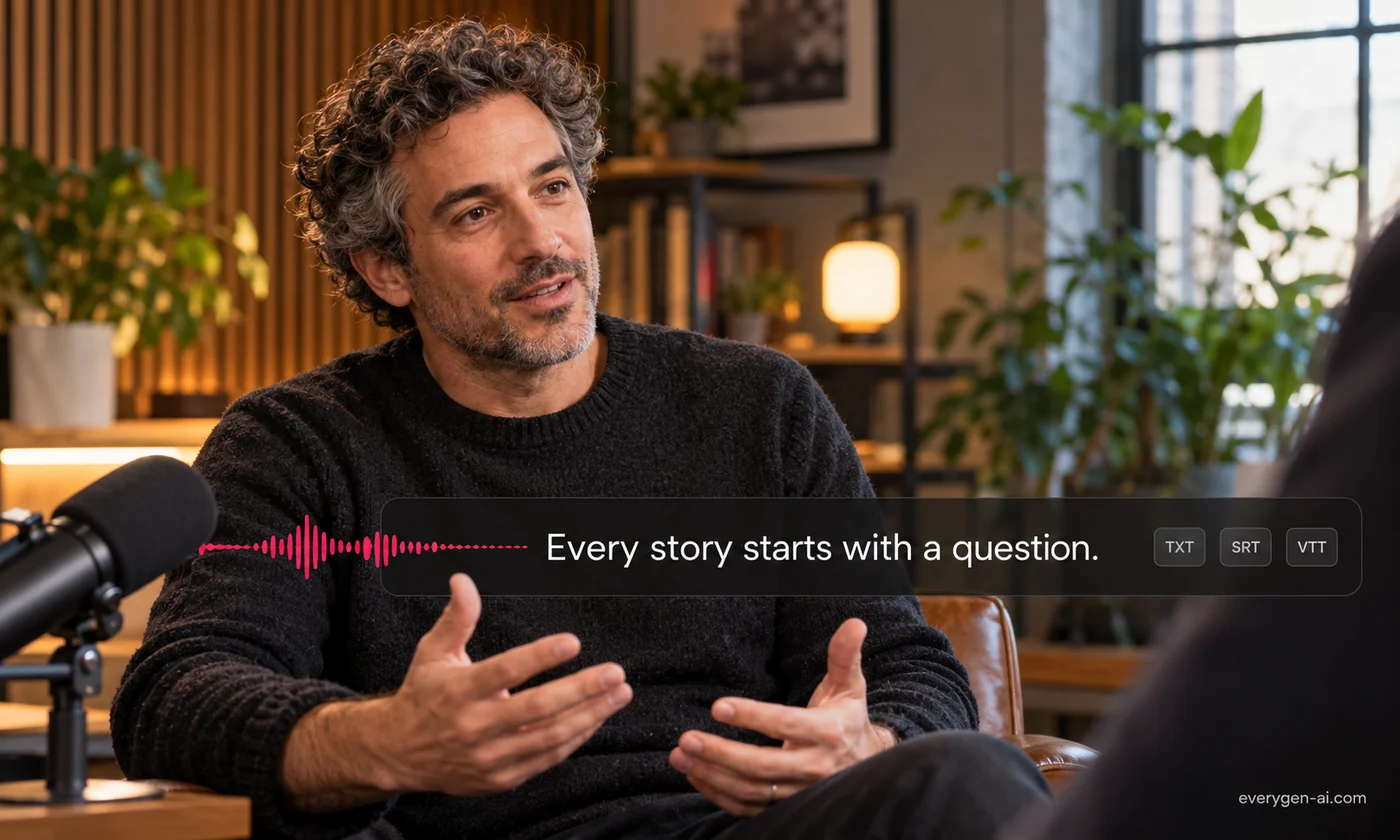
Turn recorded speech into an editable transcript, SRT or VTT captions.
Inputs, options and results.
A modern speech model transcribes the audio track, separating speakers and punctuating sentences.
Plain text suits notes and summaries; SRT and VTT keep timing for subtitles.
Most clips finish in seconds. Credits are based on the video’s length and shown before you start.
Choose your settings, then review the result.
Add a video with clear speech, up to five minutes.
Keep Auto language or choose one, then select TXT, SRT or VTT.
Generate the transcript, check names and terms, then copy it.
Places where a transcript saves time.
Turn a recorded call into searchable notes.
Give students a text version of a lecture.
Turn a video into an article, script or social post.
Formats, credits and practical limits.
MP4, MOV and WebM files up to 25 MB and five minutes long.
About 1–2 credits per minute of video, with a minimum of 1 credit. The exact price is shown before you start.
Yes. Choose SRT or VTT for timed captions.
Clear speech transcribes very well. Review names, numbers and technical terms, especially with background noise.
No. Upload a video file you have the right to use.
Upload a video and review the transcript in the editor above.